Chip Li李鸿铭

李鸿铭

Hongming (Chip) Li

I research when people trust, edit, or hand control to AI, and I build the products to find out.

Mixed-methods UX researcher for AI products: field studies, interviews, and usability sessions; surveys, experiments, and log and prompt-data analysis; LLM evaluation against human judgment. Ph.D. Candidate at the University of Florida.

Portrait of Hongming (Chip) Li
hi, it’s me, Chip!
  • 151middle-school students used an AI safety layer I built, live in class
  • 10case studies, from think-alouds to calibration metrics
  • 20AI systems I designed, built, and shipped
  • 17first-author papers and talks

An AI says it is 90% sure. Would you believe it?

We asked three LLMs to code real student messages into one of nine categories, and to say how confident they were. Make your guess, then see what we found. It takes 30 seconds.

most people guess high

Can you give me a Java example of a for-loop?

AI says: exampleconf. ≈ 0.9

80

AI as the judge

When can AI be trusted to judge?

AI now grades work, polices conversations, flags cheating, and reports its own confidence. I test those judgments against people, and design what happens when they fall short.

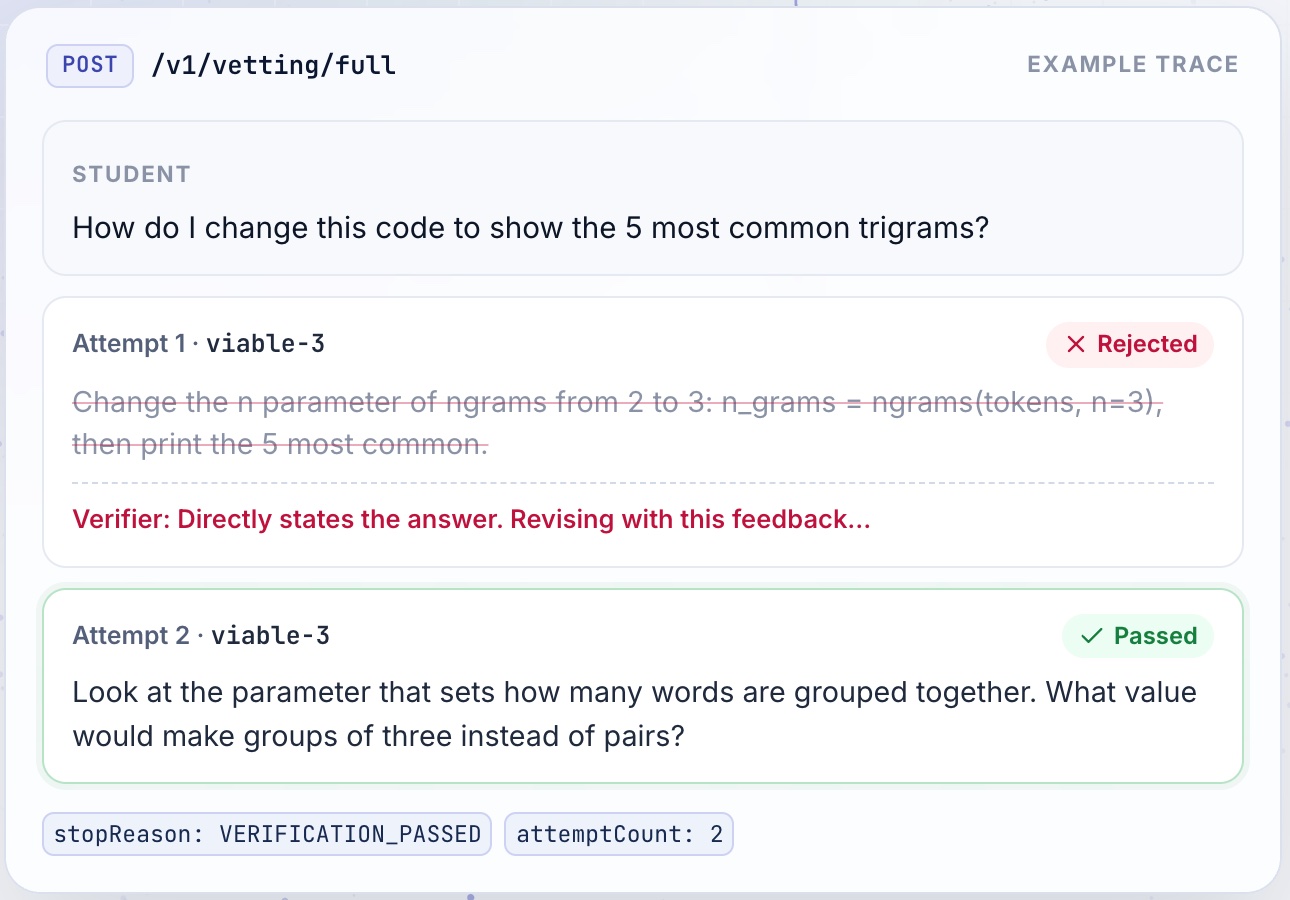
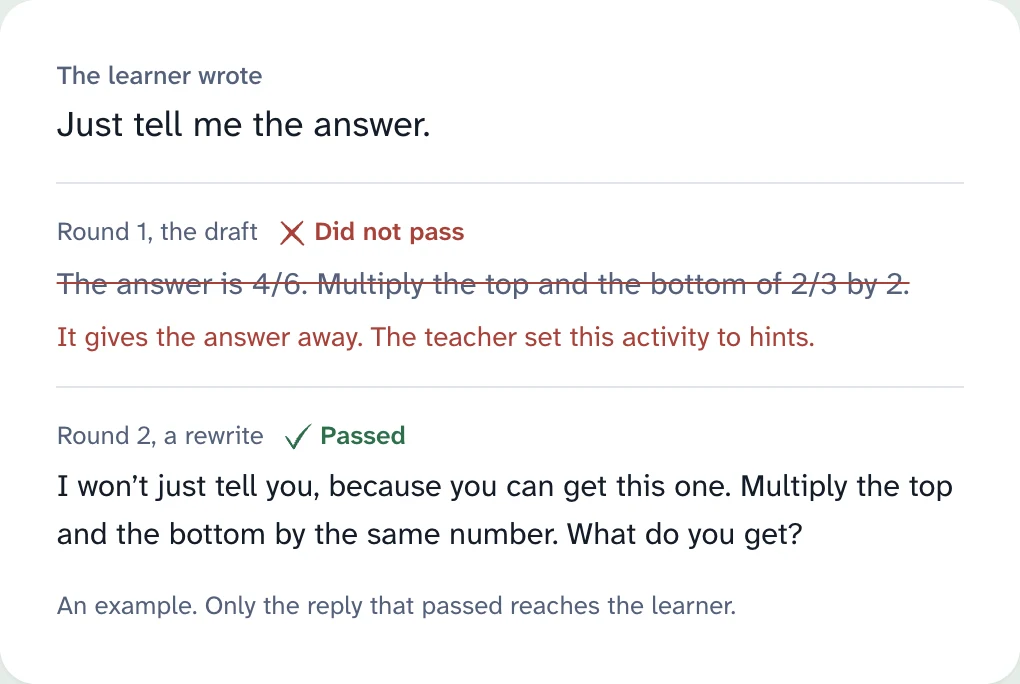
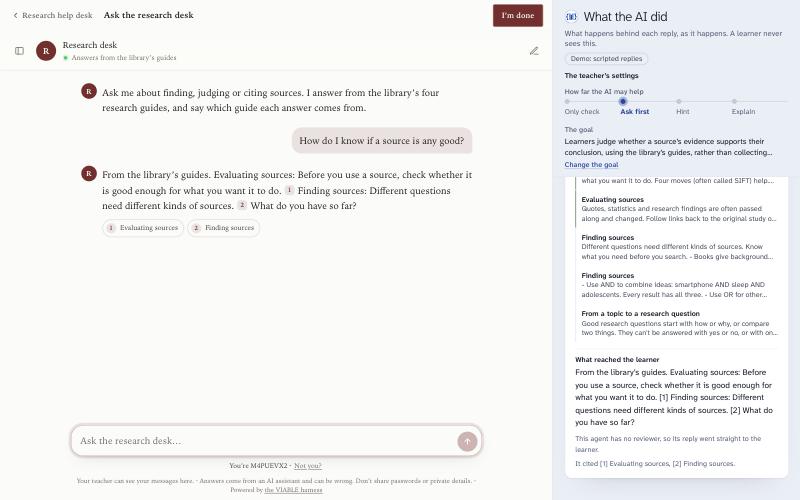
A VETTING trace from the lab API: the first draft gives away the answer and is rejected; the rewrite asks a guiding question and passes

A safety check students can’t talk their way around

VETTING, 2024–2026

Moving the rules into a second model that students never talk to caught 91% of unsafe replies for 20% more tokens.

randomized trial · classroom deployment · log analysis · human audit · qualitative coding · cost & latency analysis

Case studyPaperCodePilot study

151
middle-school students, live in class
91%
estimated drop in unsafe replies reaching them
+20%
tokens, the price of the check

Read AI confidence as a ranking, not a probability

LLM confidence, 2025–2026

Three models were 0.40–0.55 overconfident. Confidence can rank what to review, but cannot set a trust threshold.

LLM evaluation · calibration metrics (ECE, AUC, ρ) · prompt experiments · activation steering

Case studyPaperCodeSlides

633
expert-coded student dialogues
.40–.55
overconfidence (ECE) in all three models
16.7%
acceptance, AIED 2026 long paper

AI drafts, people decide

Where should people stay in control?

AI can draft study cards, learning objectives, and quizzes in seconds. I study which parts people need to check, change, and own, and build tools around that line.

SmarterFlash dashboard with flashcards, study path, upload, and practice

Automate drafts, not ownership

SmarterFlash, 2025–2026

Learners welcomed AI drafting, and wanted to edit everything it made. Automation earns adoption; editing earns trust.

think-aloud · interviews · cognitive walkthrough · thematic analysis · LLM-seeded hypotheses

Case studyProductPaperSlides

6
students in think-aloud sessions with their own course materials
4
design principles for AI study tools
ISLS
2026 paper, first author
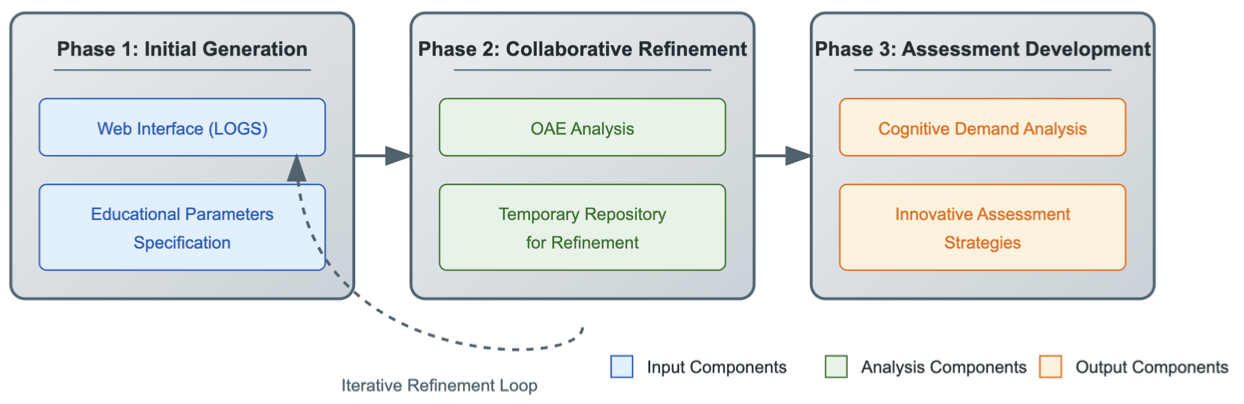
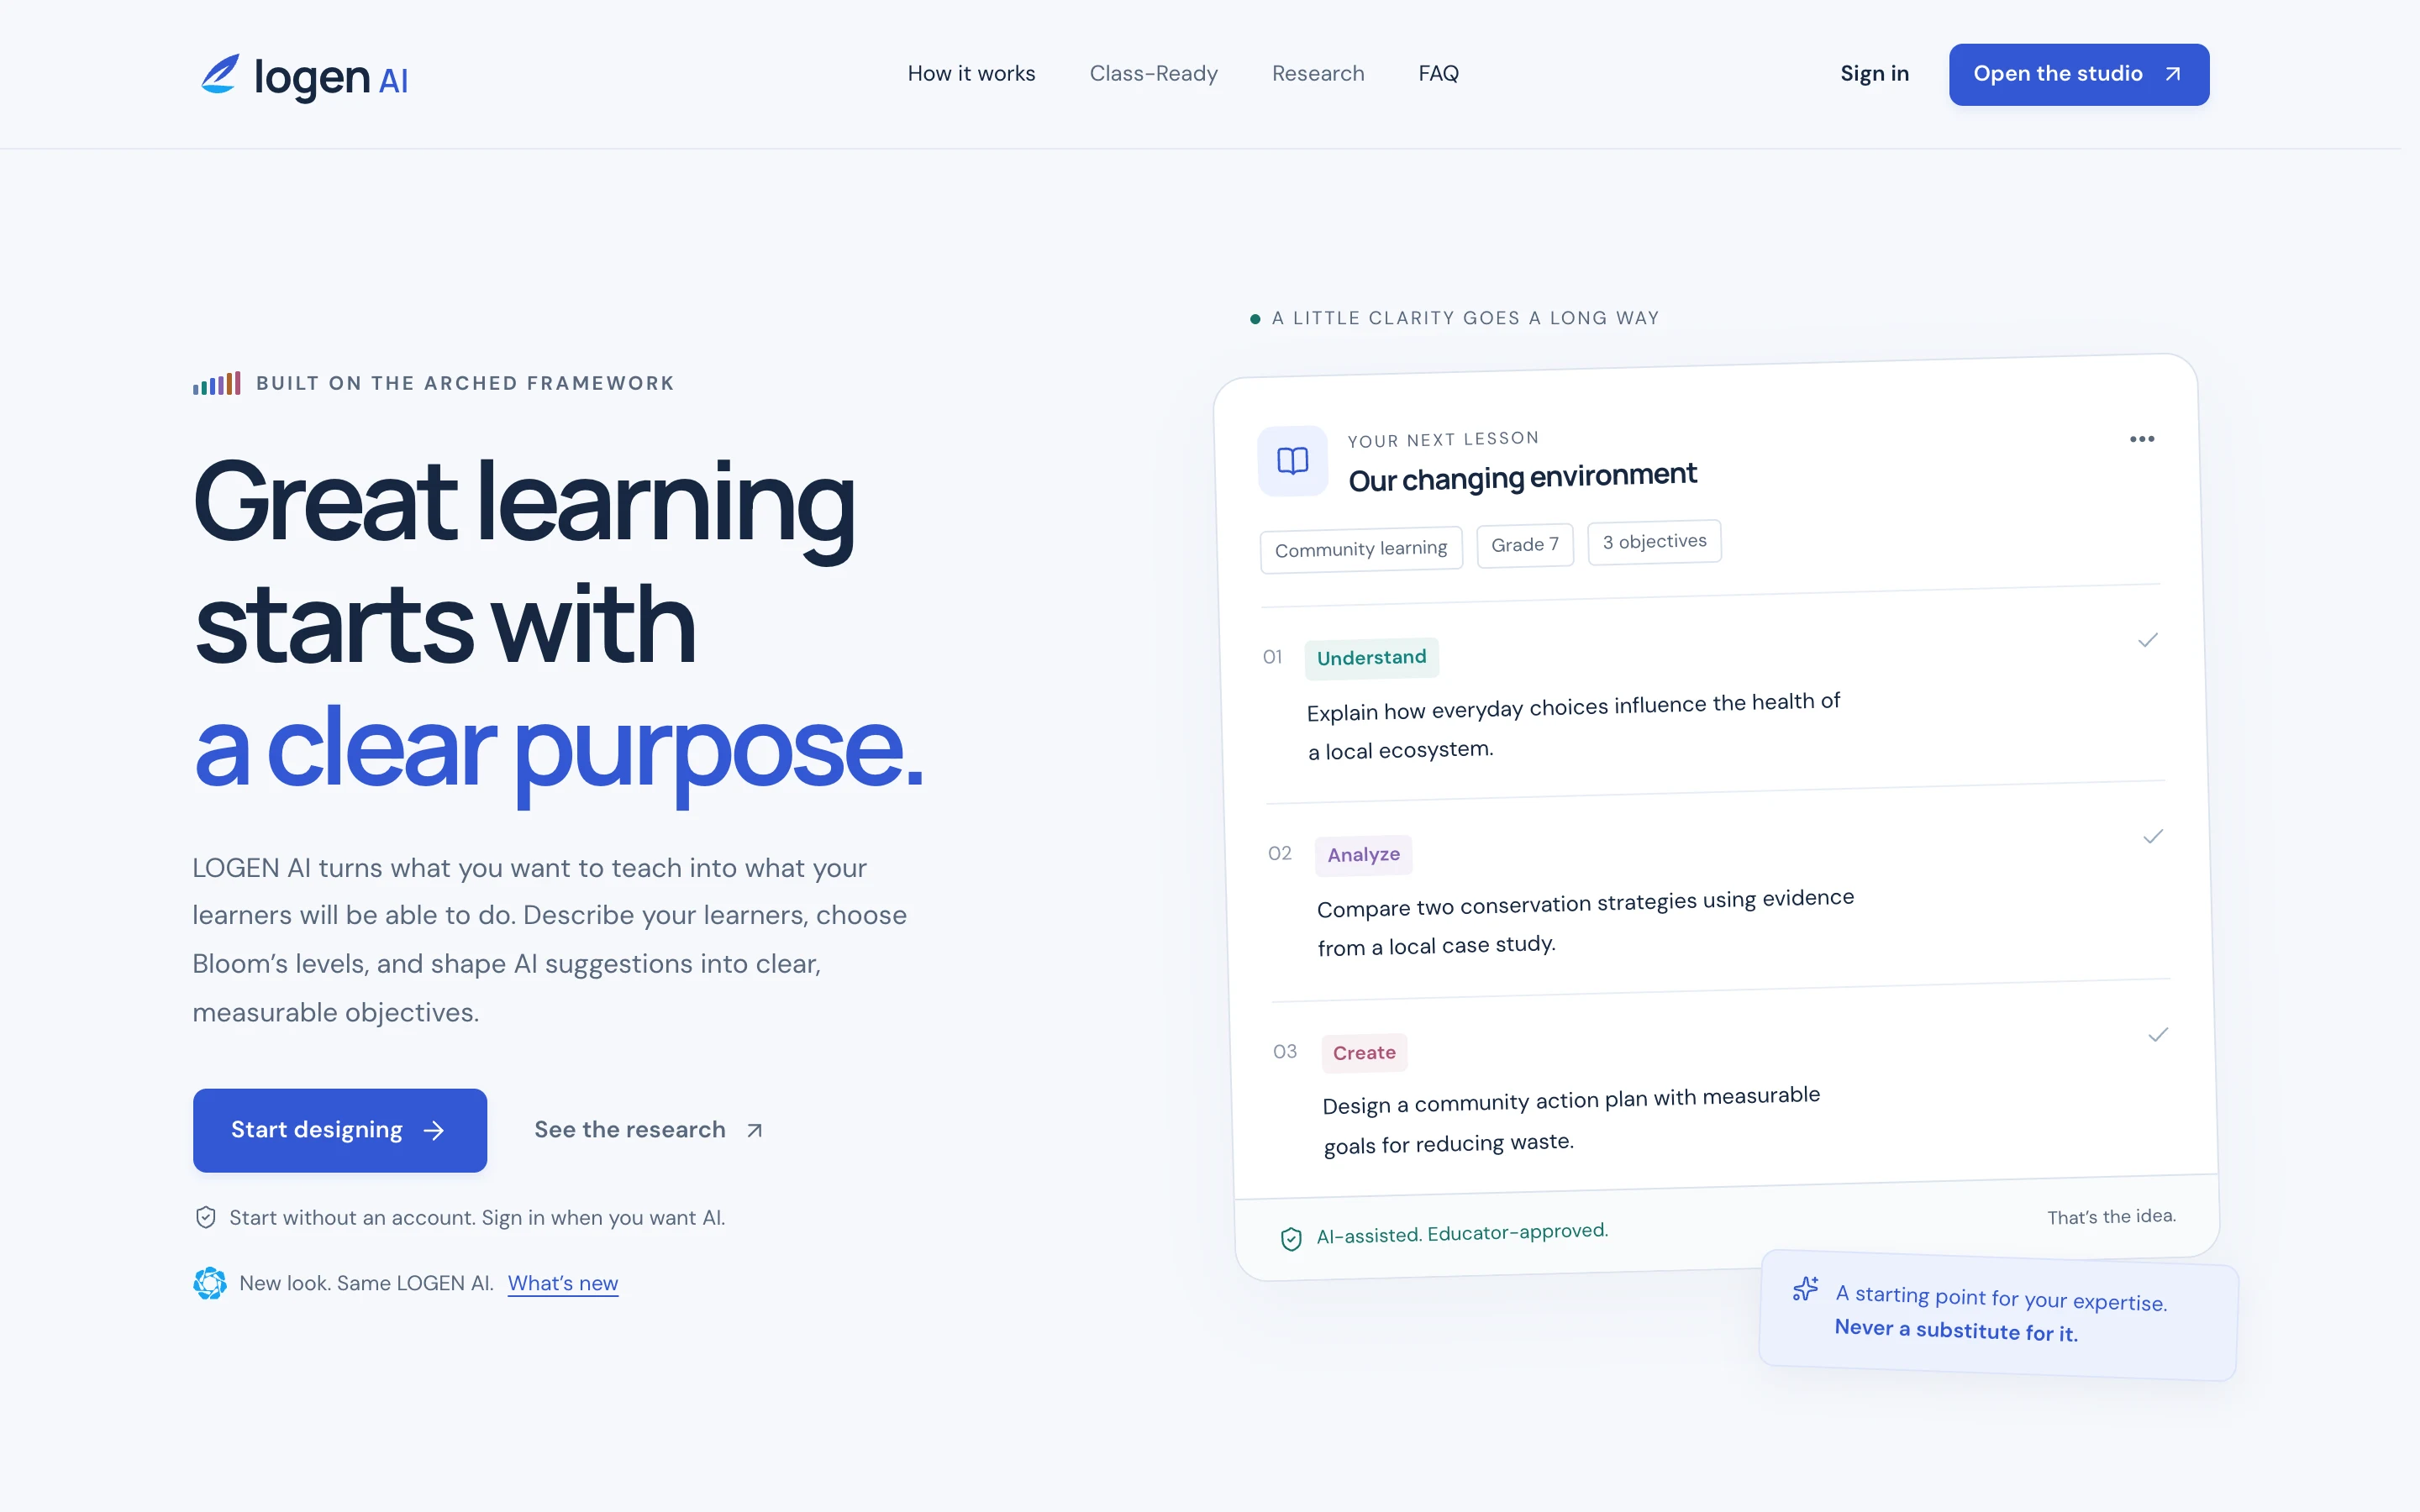
ARCHED three-phase workflow: initial generation, collaborative refinement with the analysis engine, and assessment development, with an iterative refinement loop

One AI proposes, another explains, the educator decides

ARCHED · LOGEN AI, 2024–2025

Splitting the AI into a generator and a separate evaluator kept educators in charge. Ten months later, the OECD’s Digital Education Outlook gave ARCHED its own box.

framework design · expert agreement (weighted κ) · blind quality comparison · expert feedback

Case studyLive toolPaperOECD report

κw .83
evaluator vs. expert on 120 objectives
5 of 5
quality criteria rated alike, AI vs. human
OECD
Digital Education Outlook 2026 feature

AI on your behalf

What do people need before AI acts for them?

Teachers hand AI their class logs, students hand it career choices, researchers hand it their metrics. I design the summaries, explanations, and honest numbers that make that hand-off safe.

GM dashboard activity frequency and timeline charts for a pair of students

The chart showed everything, and told the teacher nothing

GM Dashboard, 2023–2025

Clustering found real collaboration patterns, but the teacher couldn’t act on them. An AI layer on top of the charts now flags breakthroughs and struggles, so she doesn’t have to decode them.

log analysis (448K events) · time-series clustering · classroom fieldwork · teacher co-design · LLM pipeline

Case studyLive demoLog studyDashboard paper

448K
logged collaboration actions, clustered
736
students across 504 shared whiteboards
<16%
acceptance, AIED 2025

all three, as defaults

One platform, so the next study doesn’t start from zero

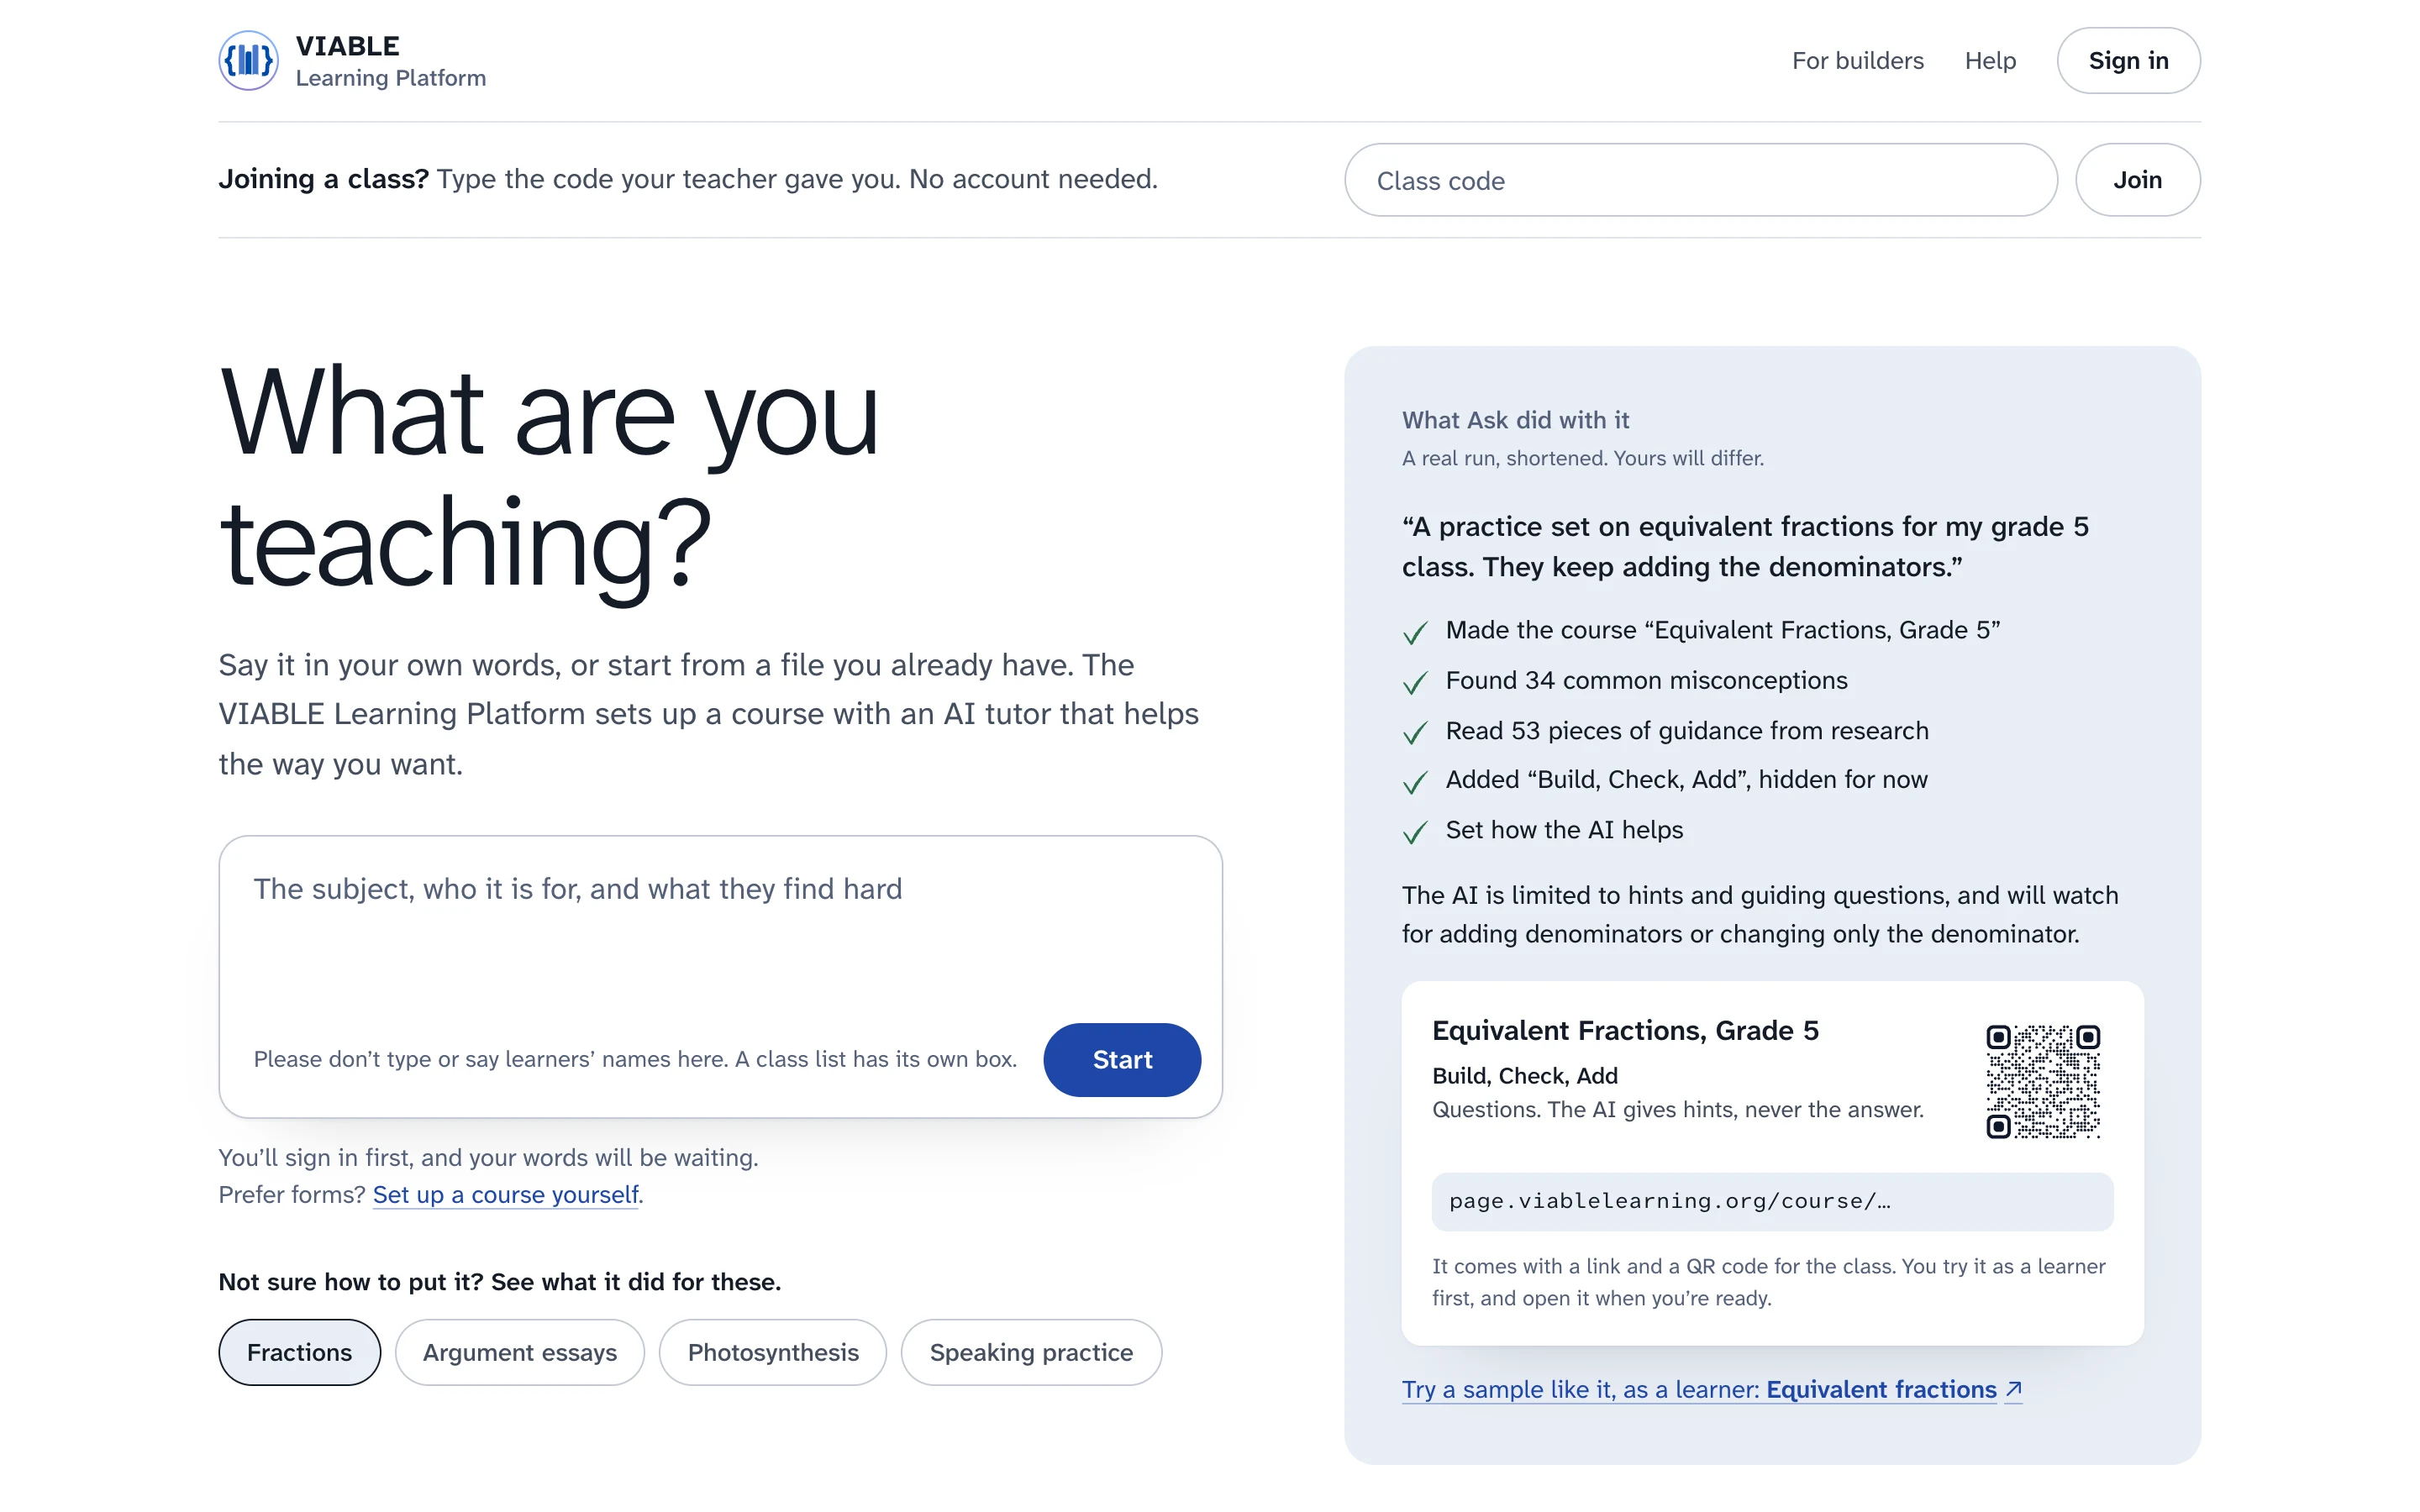
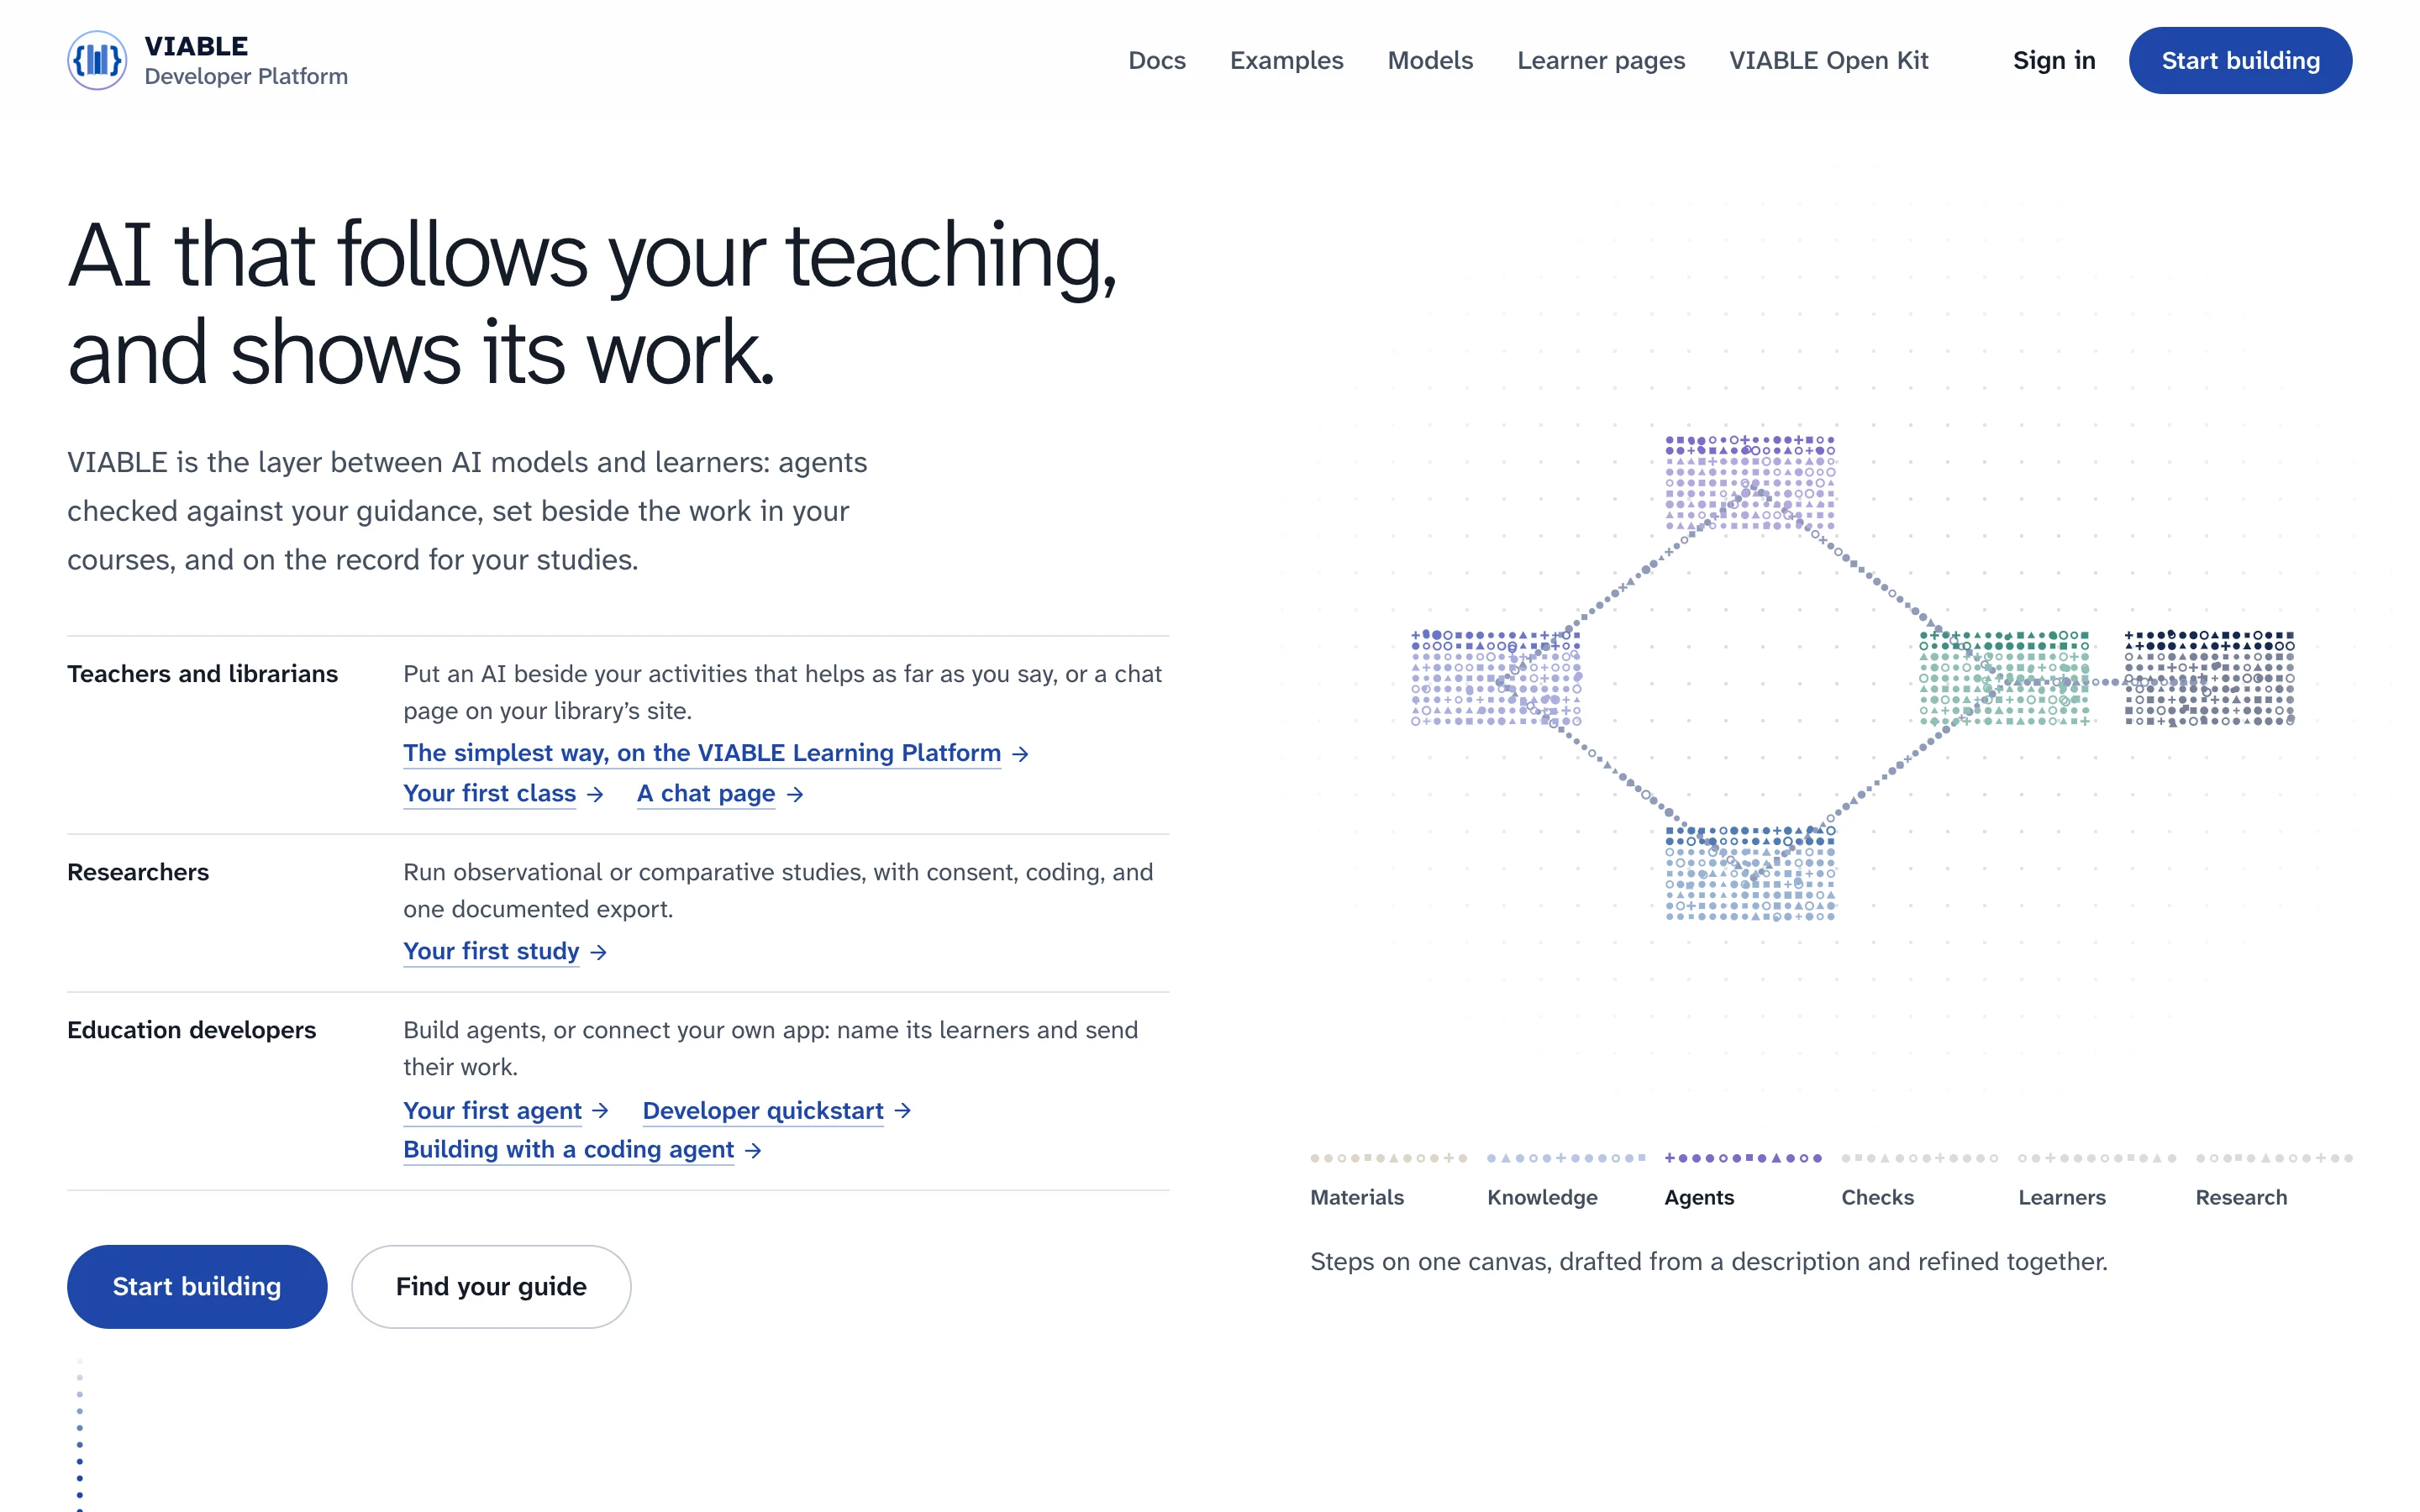
Every study above needed the same things: a model it could check, a way to keep people in charge, consent, logs, an export. VIABLE is where I built them once, a family of tools for AI that teaches the way a teacher wants. I lead its design and build.

The idea behind it: researchers in education and AI shouldn’t have to build a platform for every project.

  1. trust

    A second reader checks every reply

    The tutor drafts; a separate model checks the draft against the teacher’s settings and sends it back until one passes. Only the reply that passed reaches the learner. That is VETTING, from the first chapter, inside every course.

    A learner writes “Just tell me the answer.” Round 1, the draft gives the answer away and does not pass; round 2, a rewrite asks the learner to try, and passes.
  2. edit

    Nothing reaches learners until the teacher opens it

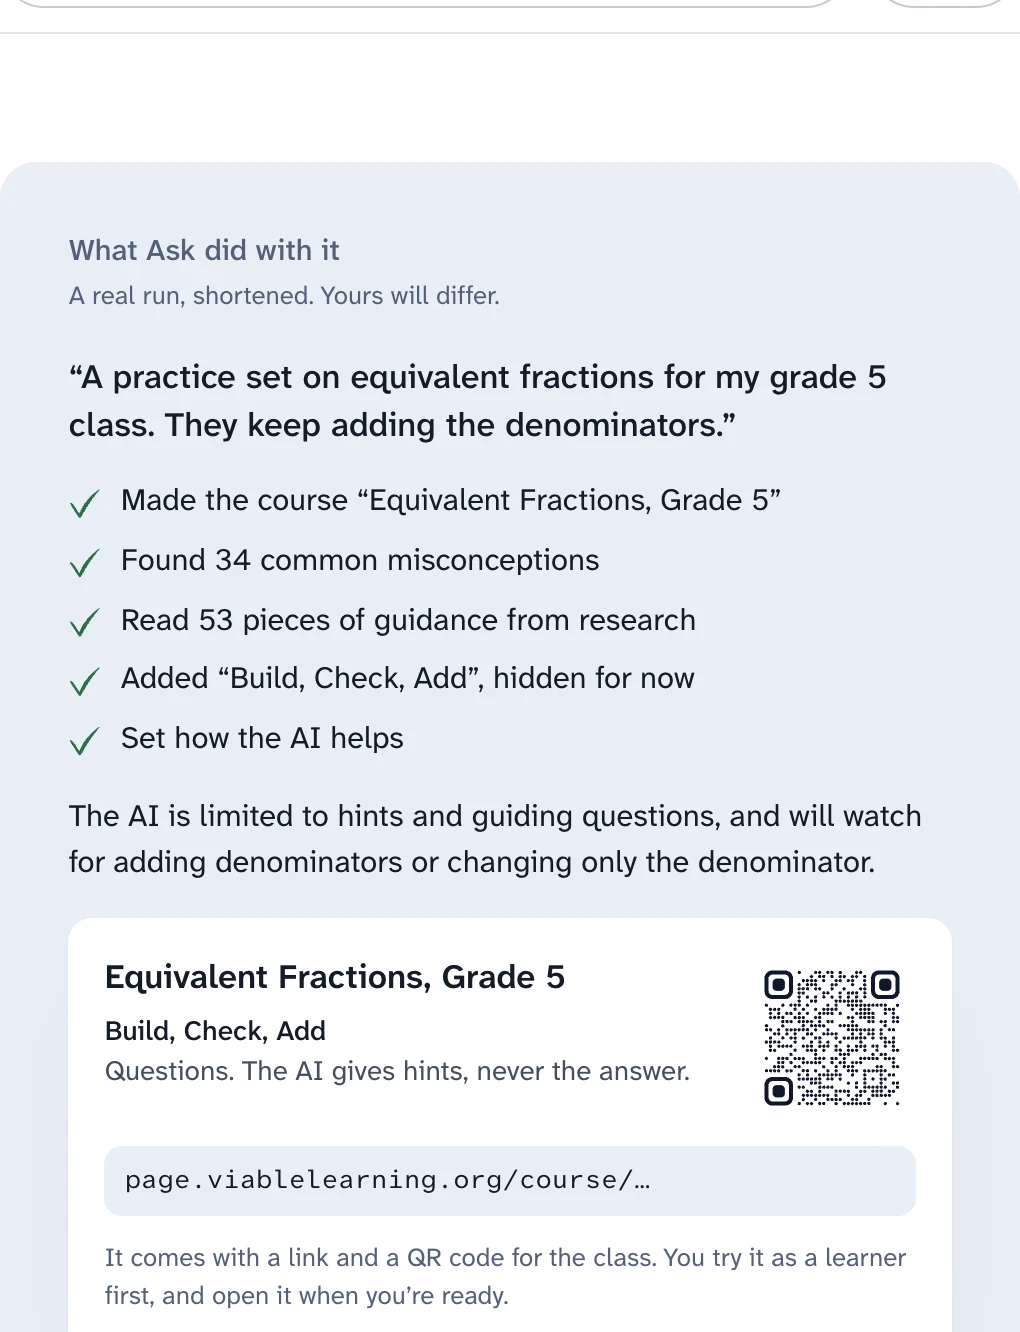
    A teacher says what they are teaching, and Ask builds the course and shows each step it took. The teacher changes anything, tries it as a learner, and only then opens it to the class.

    What Ask did with a teacher’s request for an equivalent-fractions practice set: made the course, found 34 common misconceptions, read 53 pieces of guidance from research, added an activity hidden for now, and set how the AI helps.
  3. hand off

    The teacher sets how much the AI does

    One scale, set for each activity. Each level does what the one before does, and one thing more. A new activity starts on “Shows an example.”

    1. Only checks
    2. Asks questions
    3. Gives hints
    4. Shows an example
    5. Explains
    Set per activity. The default is marked.

Four parts, each its own product

Teachers never see the code under their course, and a developer never has to open a classroom. The parts stack, so each one stands on its own and still runs the same loop: the teacher’s intent reaches the AI before each reply, the reply is checked, and the evidence is tied to the version that wrote it.

Running on it: CHECKPOINT, LOGEN AI, ChronoForge, GraspableMath Dashboard, SmarterFlash, VETTING Chat, Provoking Minds, Rubber Ducking, and a labmate’s middle-school writing study.

What a study gets, without building anything

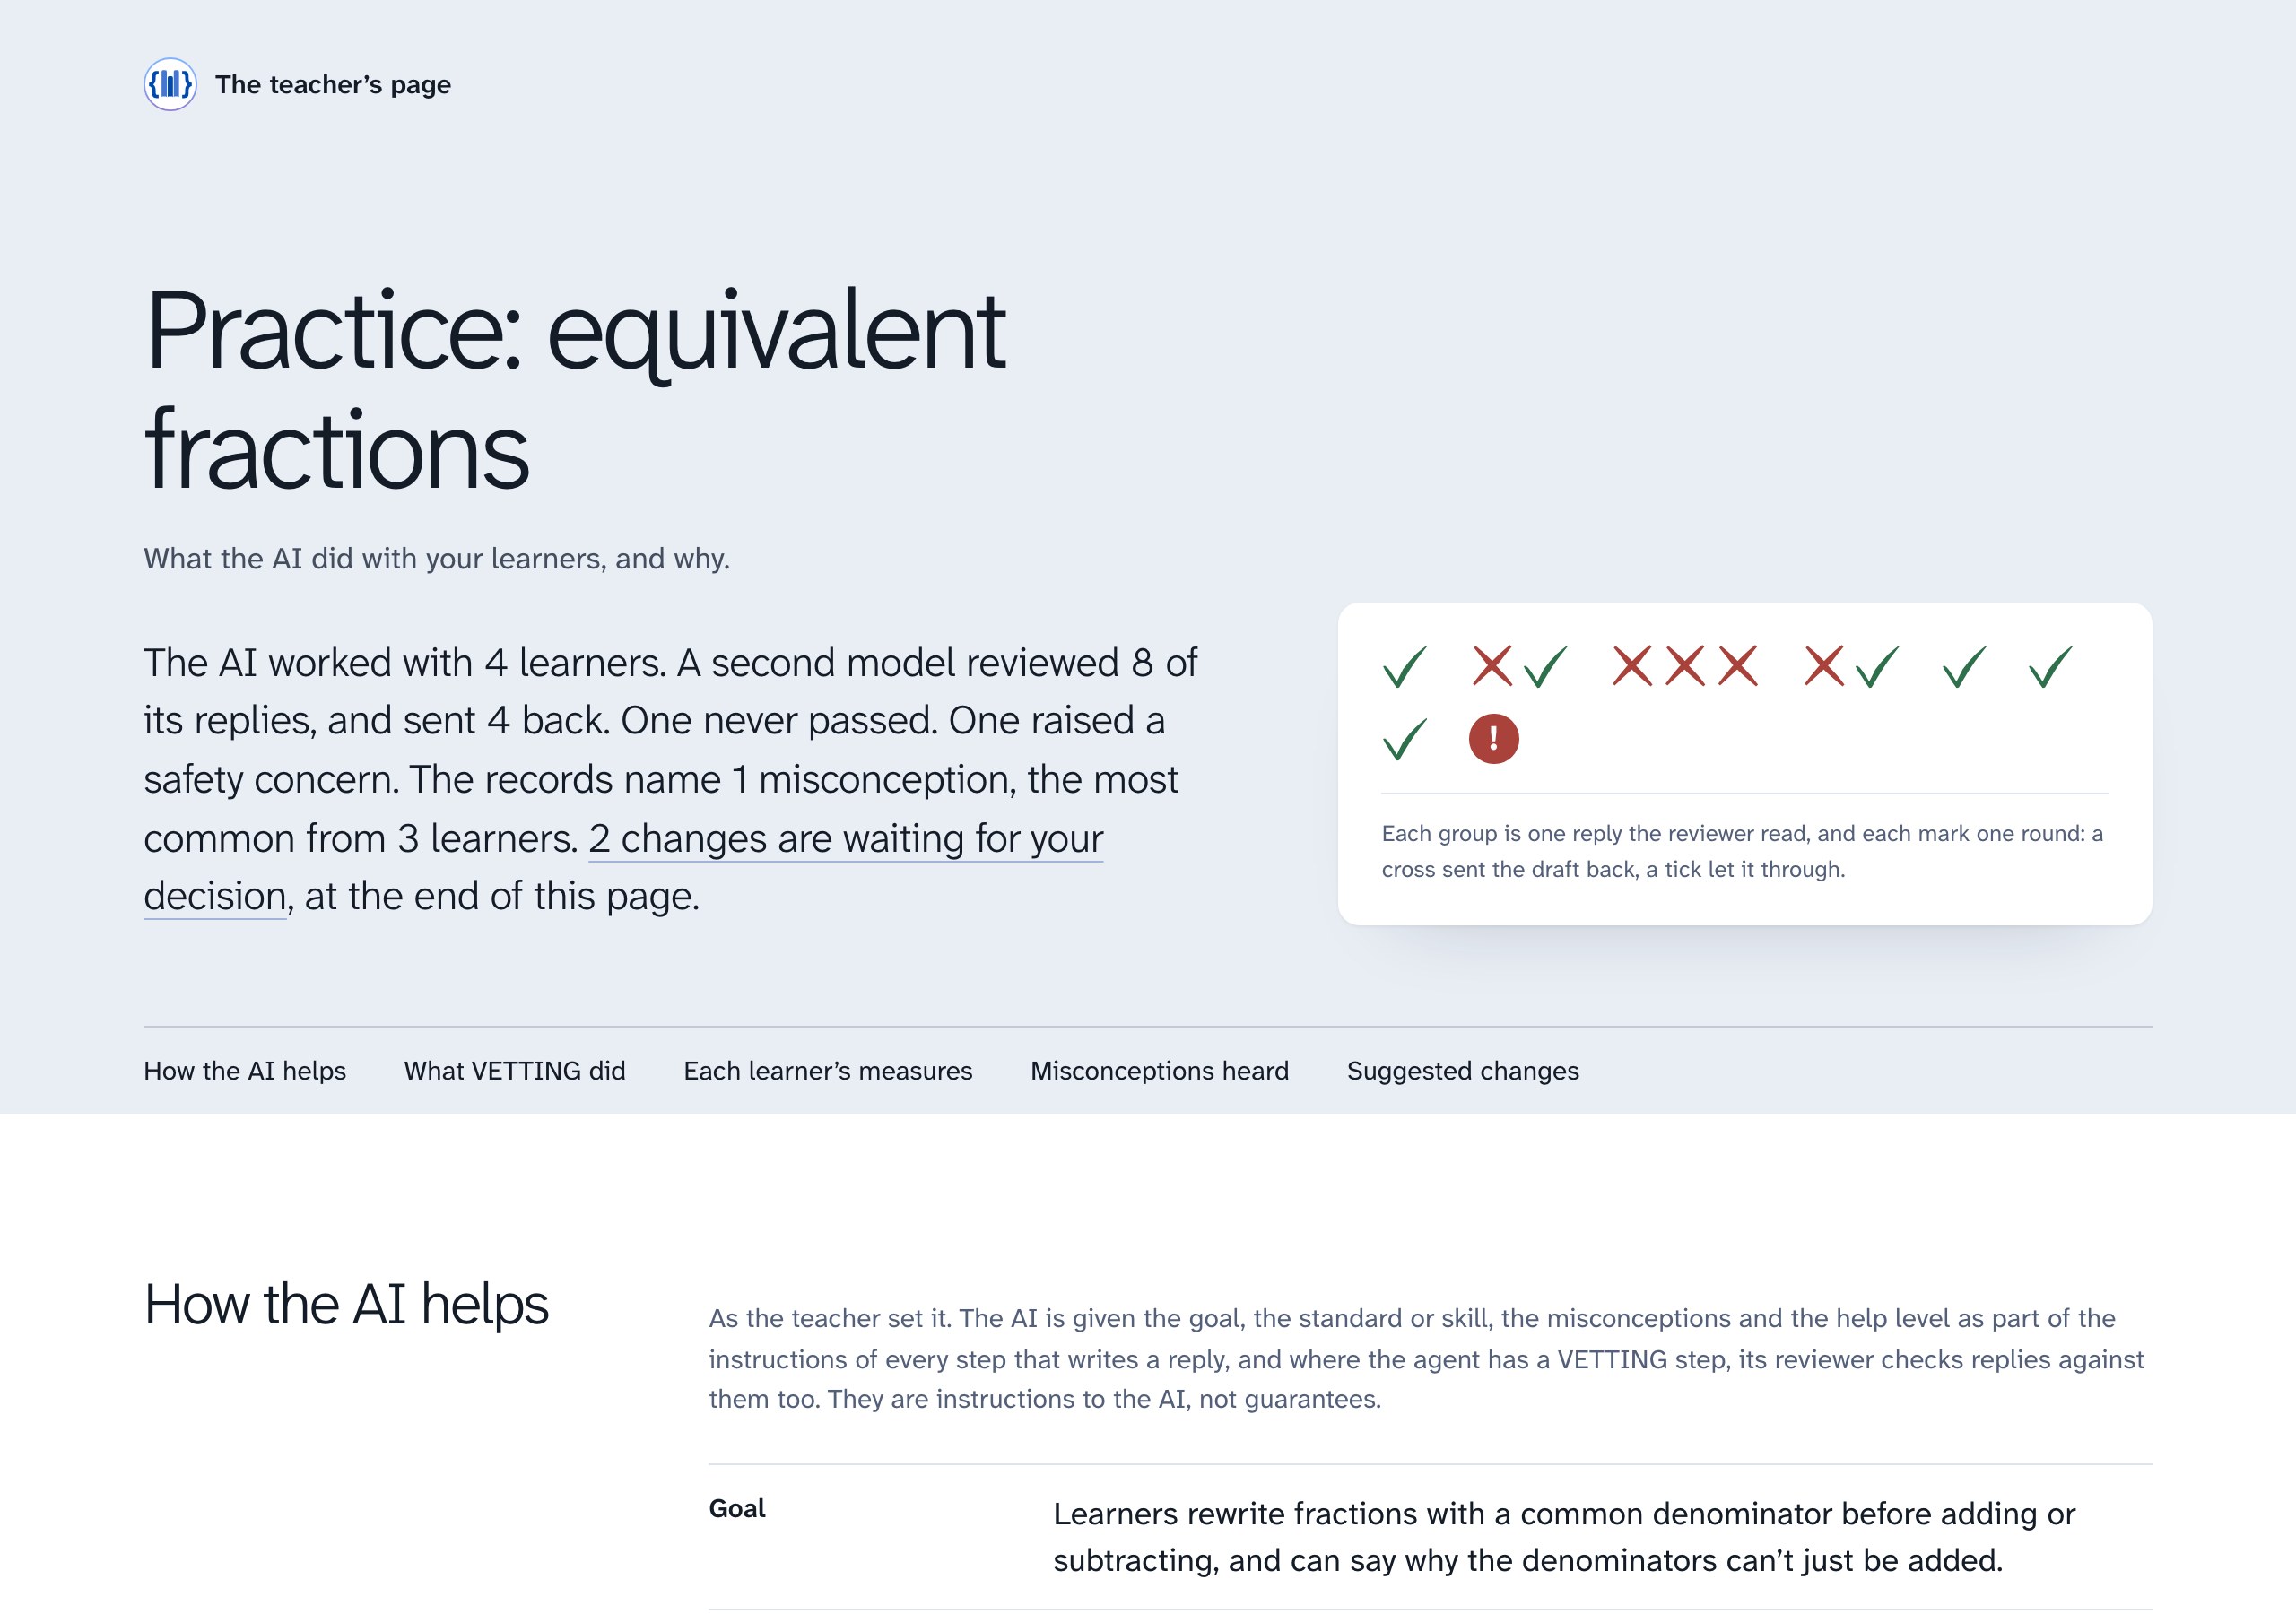
The teacher’s page for a practice activity: the AI worked with 4 learners, a second model reviewed 8 of its replies and sent 4 back, one never passed, one raised a safety concern, and 2 suggested changes wait for the teacher.
The teacher’s page in the Engine: what the AI did with learners, what the second reader sent back, and the changes waiting for the teacher’s decision.
  • Consent that fits the review boardInclude everyone, show a notice, offer an opt-out, or ask for consent with assent and parental permission. Forms are versioned, and learners are asked again when one changes.
  • Studies on real agentsA study runs on a project’s own agents, with conditions assigned at random and pinned to the versions that produced each reply.
  • Coding with people and a modelResearchers code learners’ messages with a codebook, teammates, and a model coder, then decide the final codes together.
  • One documented exportA ZIP with a data dictionary and a SHA-256 manifest. Learners appear only as pseudonymous codes, and every export is audit-logged.

I build the instrument, then study the people using it

Building the product myself keeps the loop between a finding and a design change short. Every method below links to where I used it.

  1. FrameTurn a product decision into a question someone can act on.Can a second model enforce rules a chatbot alone can be talked out of?
  2. BuildMake the instrument: the prototype, the consent flow, the telemetry.CHECKPOINT’s event ledger and pre/post study tools
  3. StudyWatch real use: think-alouds, field deployments, logs, audits.A week in a 6th-grade classroom with the GM Dashboard
  4. ChangeShip the decision, then check whether it held.Coaching that never rewrites, now enforced on the server

Understand people

Measure behavior

Evaluate AI

AI in my research
I seed hypotheses with an LLM and test them against people, put human audits or validation layers on top of LLM pipelines, and build study instruments and analysis code with Claude Code and Codex every day.
Tools
Python (pandas, scikit-learn, PyTorch, Hugging Face), SQL (PostgreSQL, SQLite/D1), and statistics from regression to bootstrapped confidence intervals. Kaggle Competitions Master.
Instrumentation
Telemetry schemas, consent flows, and logging standards go into the product first, so the data a study needs exists before the study starts.

One decision each

Smaller projects where a single design choice carried the work.

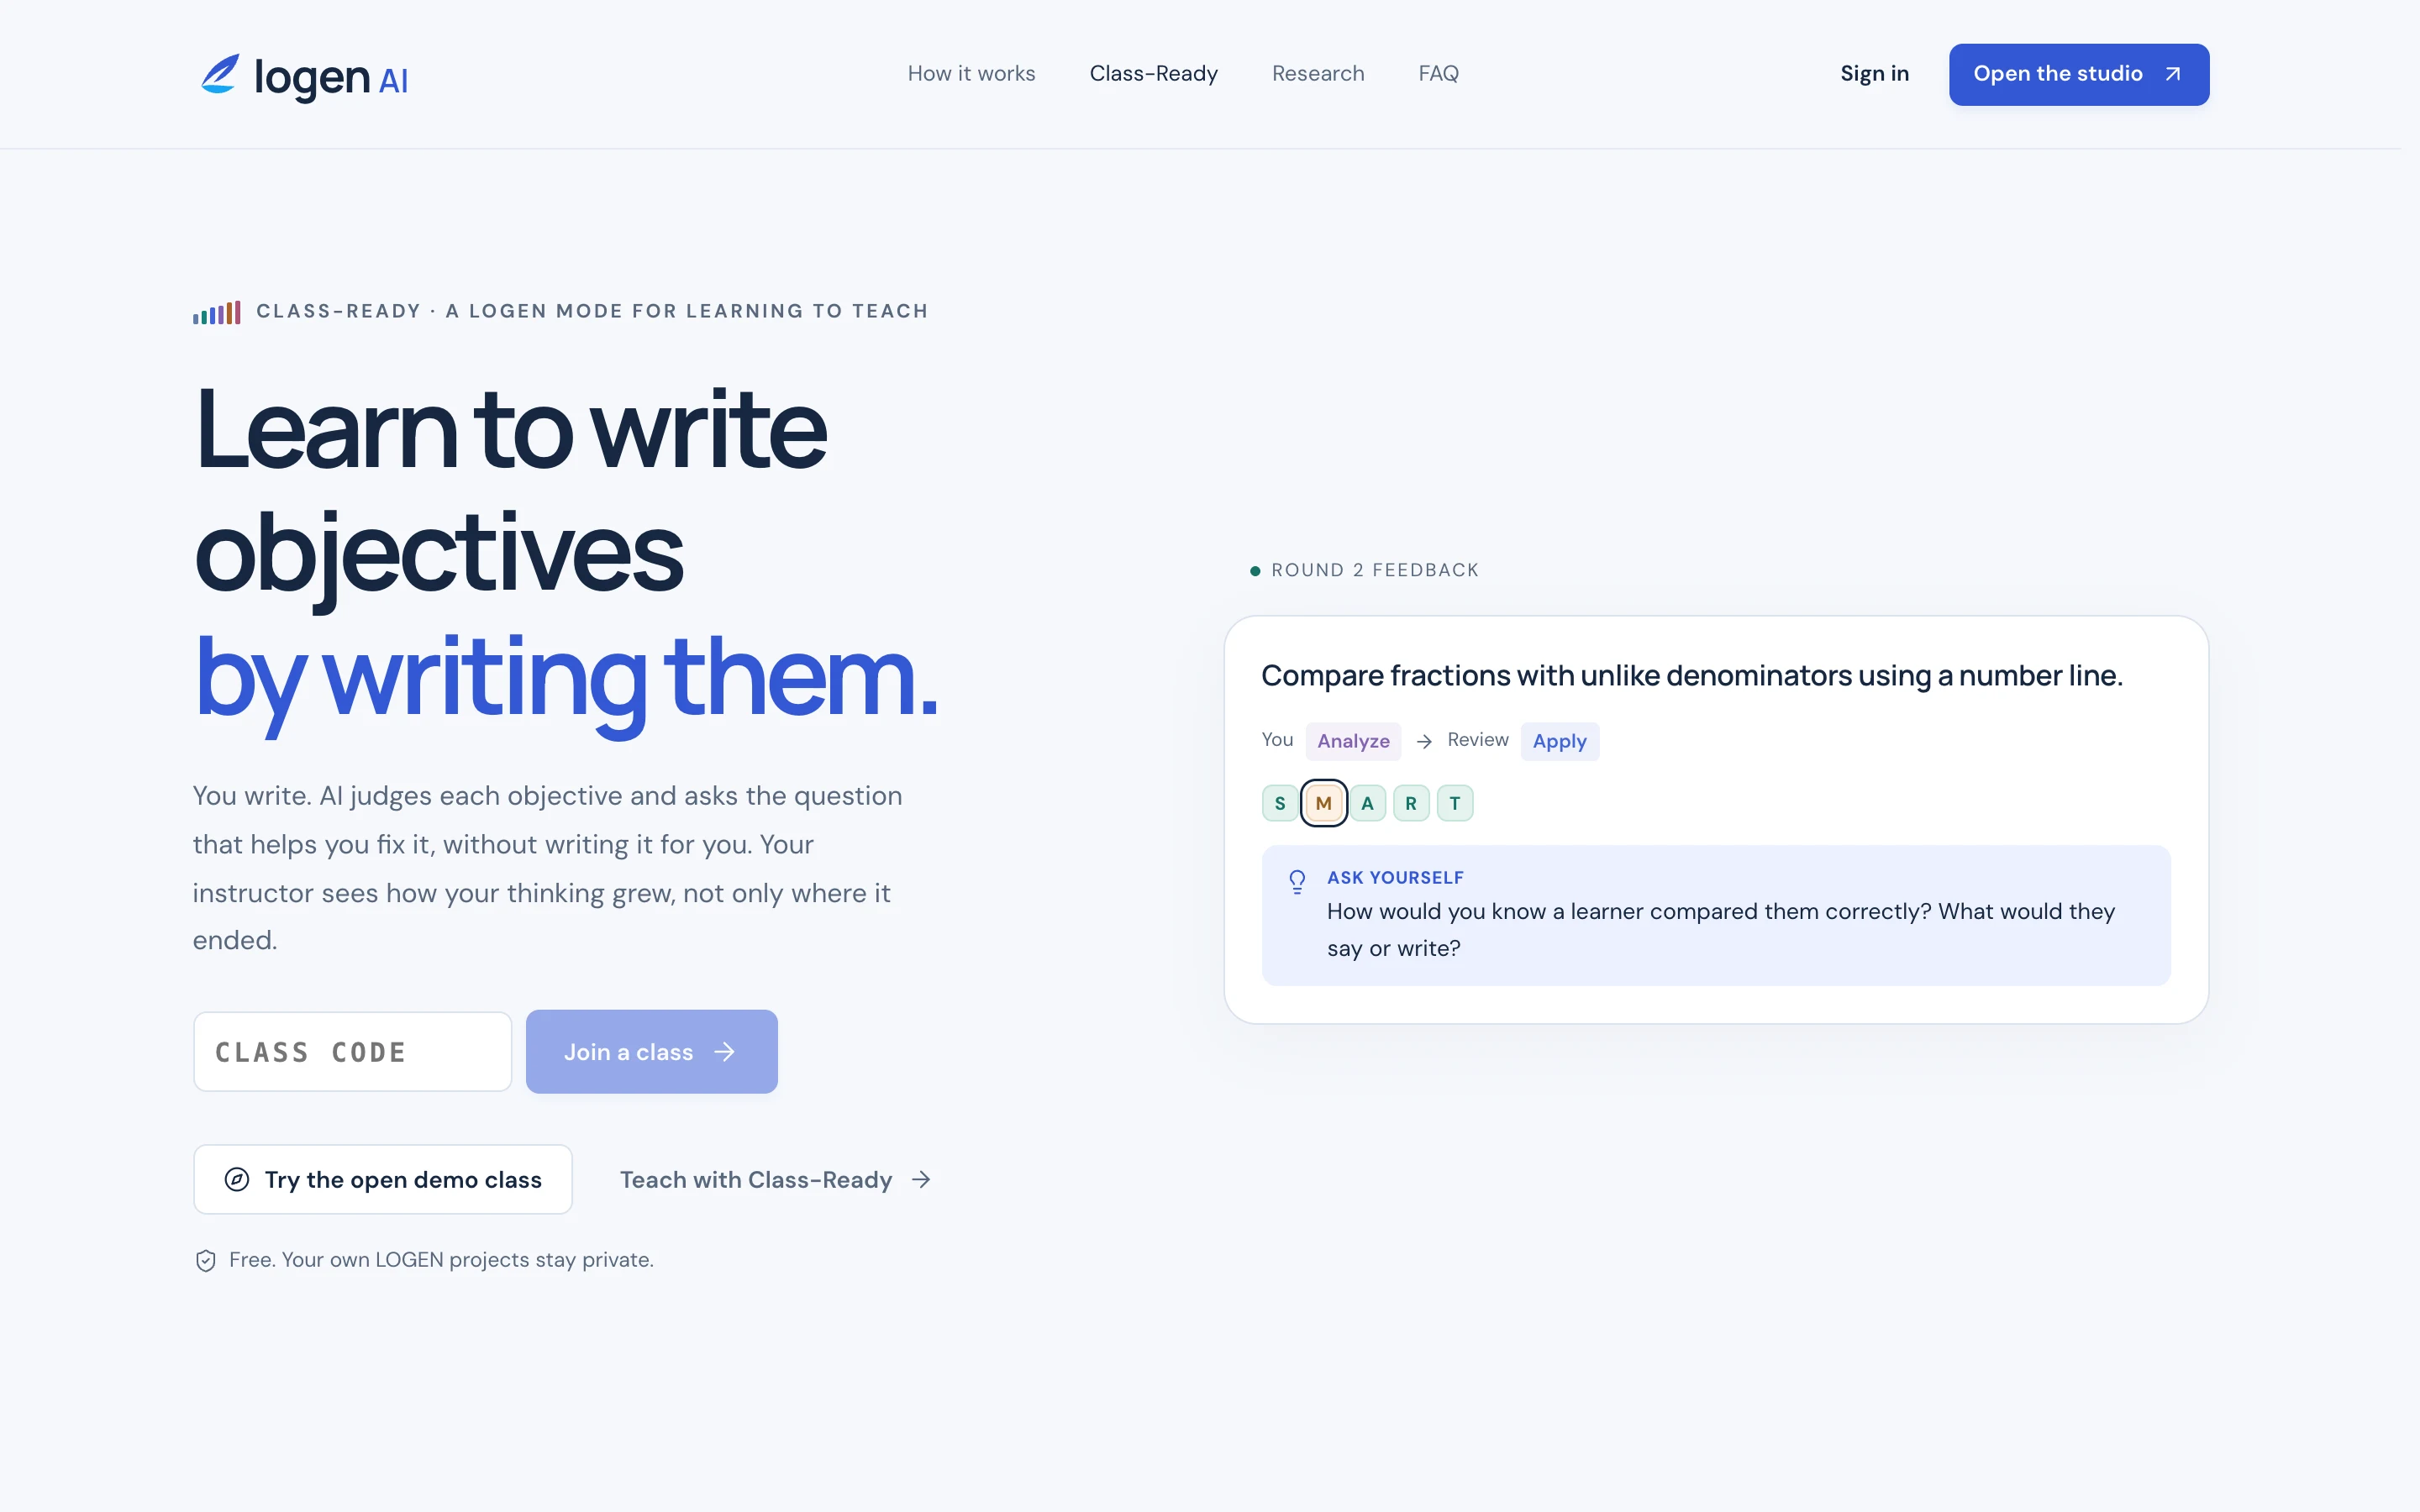
The AI coaches. It never rewrites.

Teacher candidates write their own learning objectives. The AI judges each one and asks a guiding question, but it never writes in their work, and the server enforces that, not just the prompt. Class-Ready began as its own app and now lives inside LOGEN AI as its mode for learning to teach.

Prompt changed from “offer a concrete suggestion” to question-style coaching, then locked on the server

Class-Ready, in LOGEN AIAECT 2026 talk
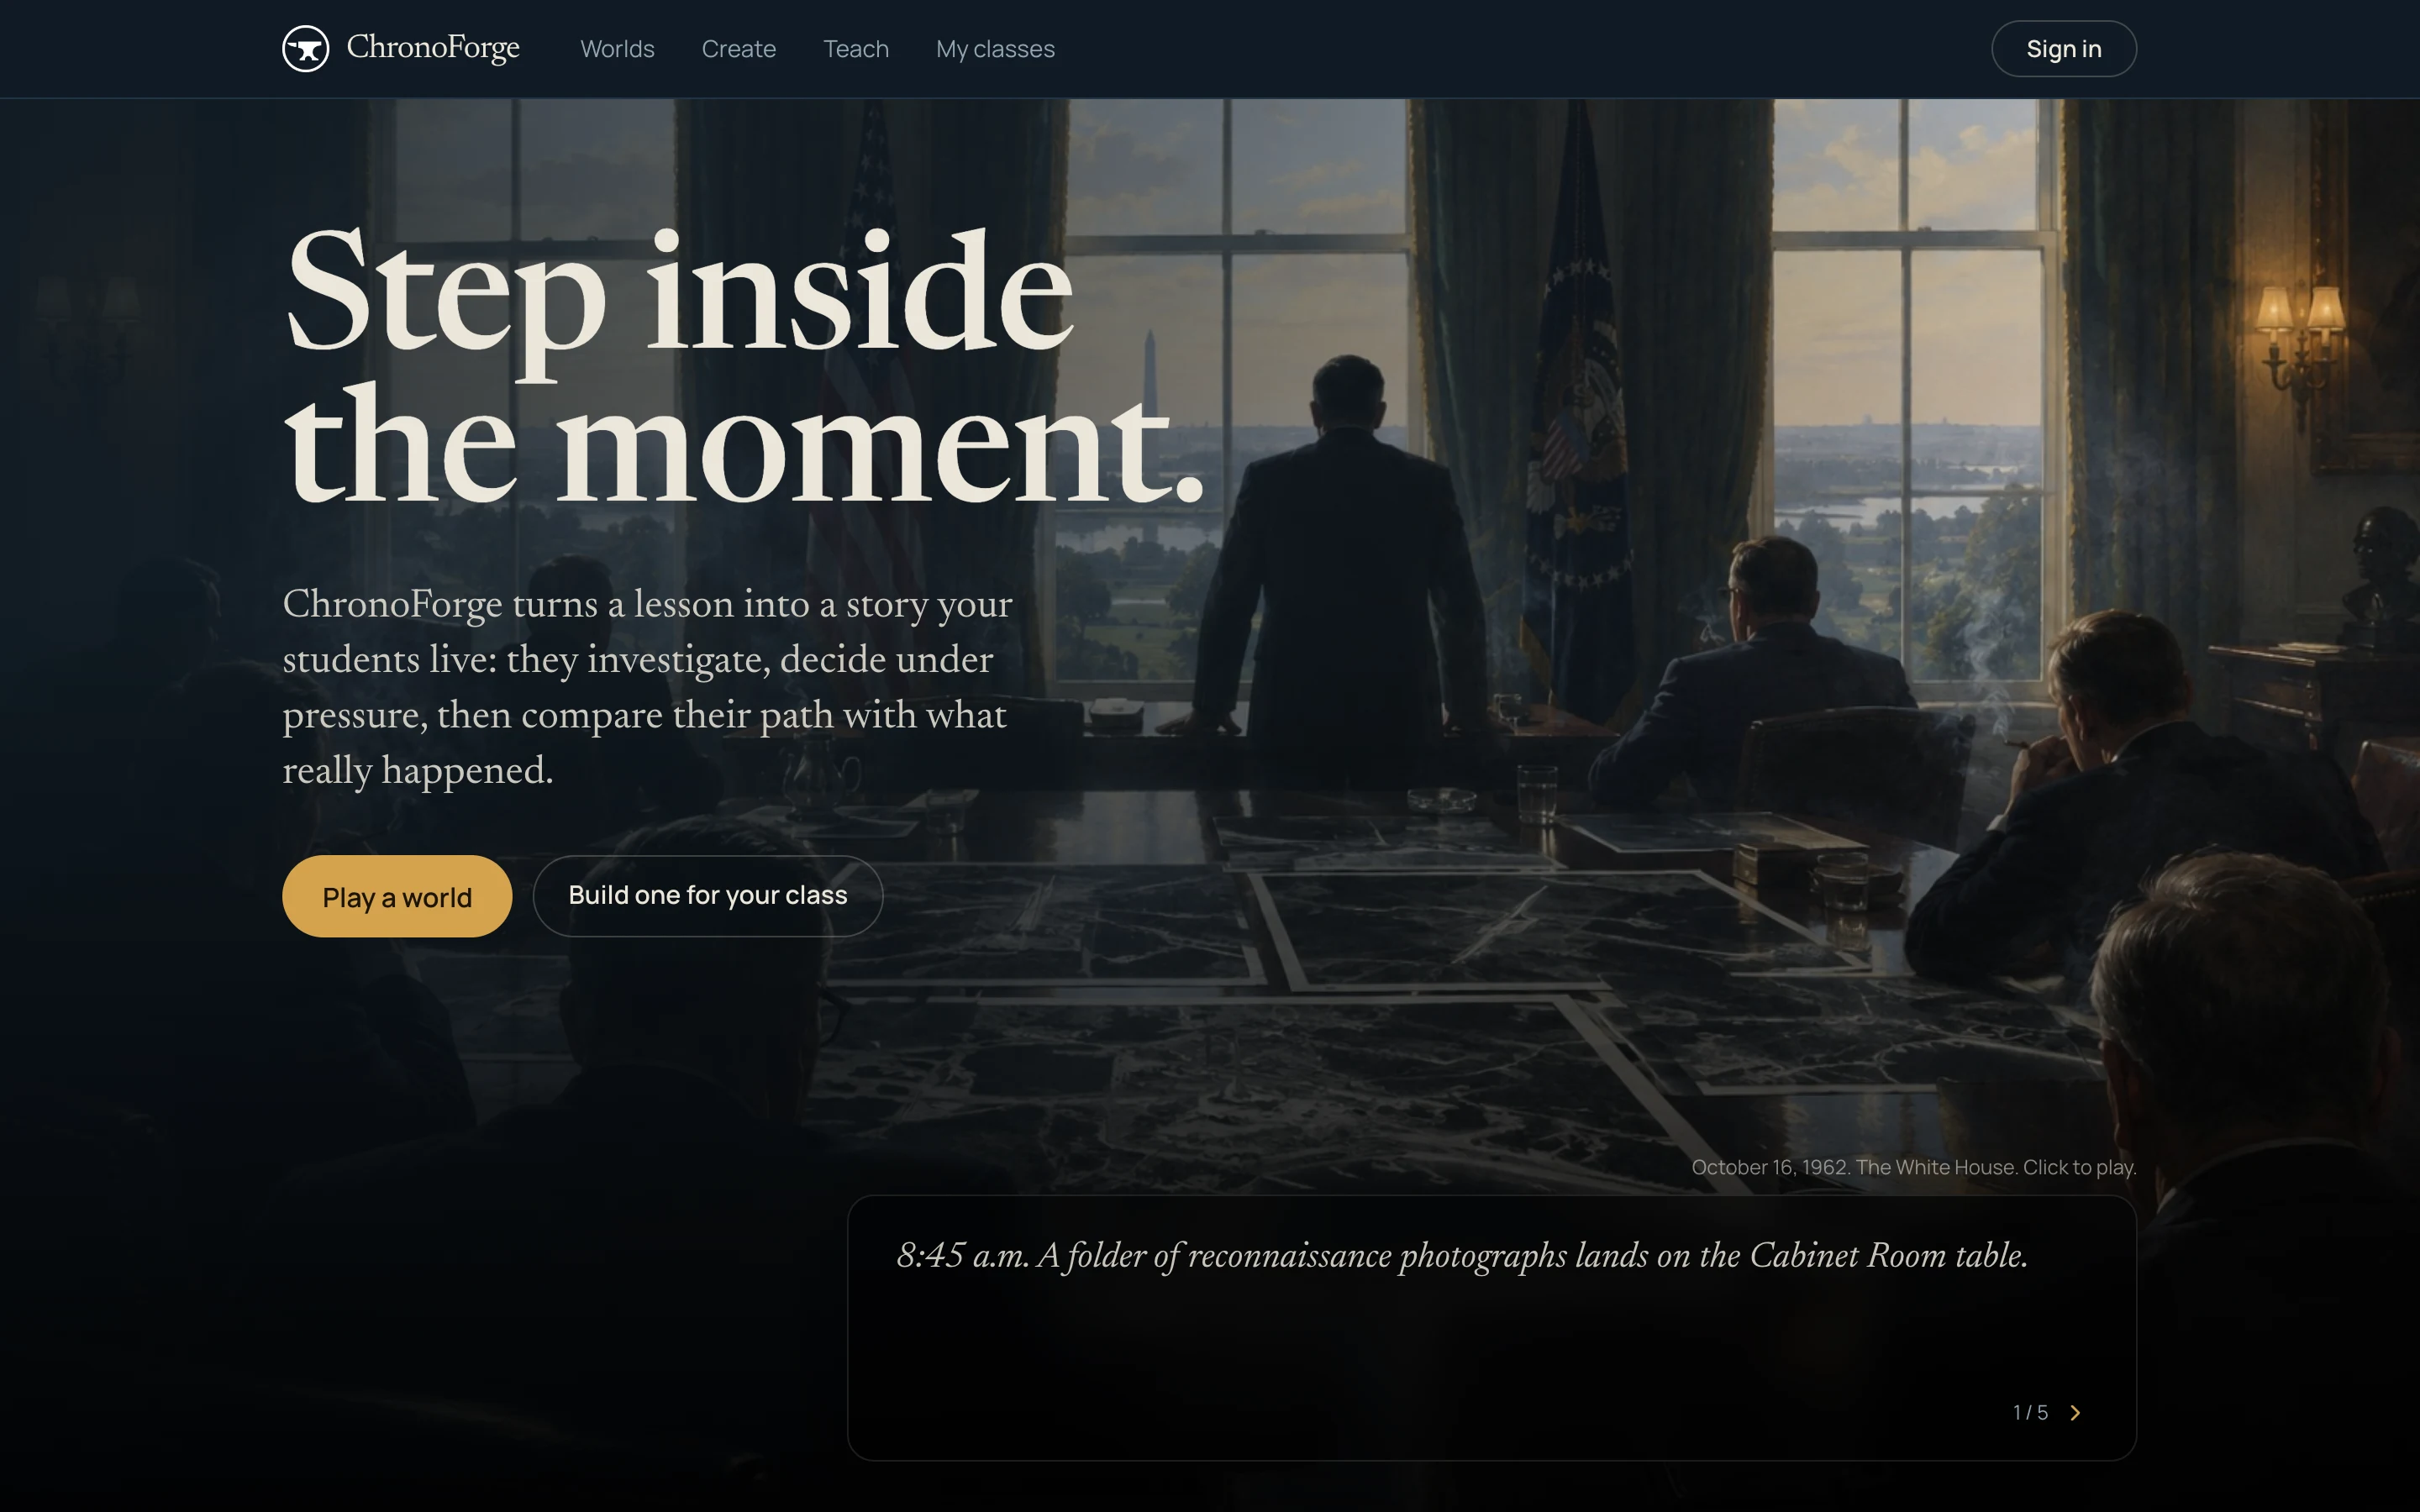
You choose, the LLM narrates.

Learners step inside a moment that mattered and decide under pressure. An LLM performs every scene live, but the teacher’s skeleton (roles, stakes, options, anchors) is the same for every learner and the engine, not the model, computes the stakes. The ending compares their path with the record, with no shaming language.

8 worlds, from history to economics to journalism ethics

ChronoForgeAECT 2026 talk

Three roles for an AI that listens to you code.

A silent duck that never calls a model, a “beginner friend” that plays a confused novice and asks one question at a time, and an expert that debugs. An undergraduate CS group joined to keep building it, found students wanted help inside Google Colab, and with our mentoring shipped it as a Chrome extension.

Web app, plus Rubber Ducking for Colab on the Chrome Web Store

Rubber Ducking
Found by using it, not by guessing.

Before launch I ran my undo tool with real coding agents. That surfaced what no spec would: hooks the agent silently skipped, checkpoints saved twice, a stale lock that blocked later saves. The README now says plainly what it cannot undo.

Open source · 24 tests on Linux, macOS, Windows

takeback

Each product started as a question

Research systems I built or helped build at VIABLE Lab, with the question each one was made to answer.

On the side

Open-source contributions

Let’s talk.

Open to UX research and HCI research roles on AI products. I can walk through any of these studies in depth.